AI Governance Evidence Lab
From AI claims to evidence-informed governance decisions
INDEPENDENT RESEARCH CONCEPT · NOVEMBER 2026
AI GOVERNANCE EVIDENCE LAB · RESEARCH CONCEPT
From AI Claims to Evidence
How can we tell whether claims about AI systems are credible enough to inform governance decisions?
AI developers and deployers make claims about safety, fairness, and social benefits. This project explores what evidence supports those claims, what conclusions can reasonably be drawn, and what decision-makers should do when important uncertainties remain.
THE PURPOSE
A claim is not the same as evidence, and evidence is not the same as proof.
The Lab is an early-stage research framework for tracing AI-related claims to supporting information - such as evaluation results, audit reports, documentation, or observed outcomes - and asking what that information actually establishes. The intended contribution is a transparent way to analyze evidence quality and its implications for oversight, not a new tool that automatically certifies AI systems.
Research case study: Can AI make hiring fairer?
One possible research direction. AI-assisted recruitment is a useful test case because AI developers (such as companies providing automated CV screening and candidate-ranking tools) may claim that their systems make hiring fairer, while applicants, employers, and regulators need to know whether the evidence supports those claims.
“Our AI system reduces discrimination in hiring.”
What would we need to know before relying on this claim?
Why this matters in practice: Governments are already confronting these questions.
In the UK, official guidance discusses evidence of bias audits, while the Information Commissioner’s Office has investigated AI recruitment tools.
In the US, New York City’s Local Law 144 requires bias audits and public summaries of their results for covered automated employment decision tools.
Meanwhile, the EU AI Act classifies certain AI systems used in recruitment as high-risk, establishing additional requirements for their providers and deployers.
These examples raise a common research question: What evidence is sufficient to demonstrate that an AI system is fair, reliable, and suitable for real-world use?
Potential research output:
A comparative study of publicly documented claims about fairness in AI-assisted recruitment, examining the evidence used to support them, the strength of the conclusions that can be drawn, and the implications for governance.
The study could produce a structured evidence matrix and a policy paper identifying gaps in current evaluation practices and recommending ways to improve transparency, accountability, and regulatory oversight.
How the Evidence Lab Approaches the Problem
The Evidence Lab is built around three interconnected questions: how to assess the credibility of evidence about AI systems, determine what conclusions it supports, and translate those findings into informed governance decisions.
What makes AI governance evidence credible?
How should decision-makers assess the provenance, independence, limitations, and reproducibility of developer claims, evaluations, audits, and incident reports? Which claims are actually supported?
What do evaluations tell us about real-world outcomes?
Under what assumptions do benchmark results, pre-deployment tests, monitoring data, and observed incidents generalize to real-world risks or benefits? Where could statistical or causal methods improve inference?
When should evidence change a governance decision?
What evidence thresholds and escalation procedures could inform deployment, monitoring, disclosure, independent evaluation, or regulatory intervention? How should institutions act when uncertainty remains substantial?
How We Investigate These Questions
The Evidence Lab combines policy research, comparative case studies, and quantitative analysis to examine how AI-related claims are supported by evidence and how that evidence can inform governance decisions.
Map evidence requirements
Compare public evaluation, assurance, and governance approaches; identify which decisions they support and what information they require.
Analyze selected cases
Trace claims to underlying evidence in a small, transparent sample; code gaps, uncertainty, incentives, and limitations. Interviews are optional and subject to access.
Test decision implications
Develop a decision-focused comparison of evidence thresholds or review triggers; use quantitative analysis only where justified by the available evidence.
Research integrity and limits
A model-generated summary is not independent verification. An audit is not necessarily evidence of real-world safety, and an observed association is not necessarily a causal effect. This concept calls for traceable sources, explicit assumptions, consideration of affected parties, and clear separation between empirical findings and normative judgments. No evidence collection, interviews, model evaluations, or empirical validation have been completed for this concept.
From Research to Policy Recommendations
EXPECTED CONTRIBUTION
Central question: What evidence should decision-makers require before relying on claims about AI systems?
The Evidence Lab aims to translate research into actionable insights for AI governance. An initial contribution could be a comparative study of publicly documented AI evaluation and assurance practices, examining the credibility of supporting evidence, identifying gaps and limitations, and assessing their implications for governance decisions.
The research could produce a policy paper or research report, accompanied by a structured evidence matrix that documents the supporting evidence, its limitations, and the conclusions it can reasonably support. Together, these outputs would offer practical recommendations for strengthening transparency, accountability, and regulatory oversight.
About me
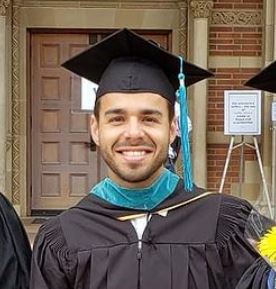
Caio Velasco · Data Science · Economics & Public Policy
I am a Brazilian mechanical engineer (UFRJ) with a Master’s in Economics & Public Policy from UCLA (Lemann Foundation scholarship). I have worked internationally in data science, applied econometrics, machine learning, and data engineering, building production data platforms and collaborating with technical and business teams across the US, Europe, and Brazil.
My academic path has also been supported by recognition from UCLA, Lemann Foundation, General Electric Foundation, Yale University, and the Club of Rome.
My research interest: bringing quantitative rigor and a public-policy perspective to questions about AI governance, credible evidence, and institutional decision-making.
This is an independent, exploratory research concept, not a functioning software system, a completed empirical study, an official assessment, or an endorsed project of any fellowship or research organization. All methods, case studies, and potential deliverables are proposals subject to further research and feasibility assessment.
© 2026 Caio Velasco. Original concept and writing. Referenced methodologies remain attributable to their respective authors.